Showing posts with label Mechanical Sympathy. Show all posts

Thursday, 26 June 2014

Notes on False Sharing

{This post is part of a long running series on lock free queues, checkout the full index to get more context here}
I've recently given a talk on queues and related optimisations, but due to the limitations of time, the Universe and Everything else had to cut short the deep dive into false sharing. Here however I'm not limited by such worldly concerns, so here is more detail for those who can stomach it.

What mean False Sharing?

Described before on this blog and in many other places (Intel, usenix, Mr. T), but assuming you are not already familiar with the issue:
"false sharing is a performance-degrading usage pattern that can arise in systems with distributed, coherent caches at the size of the smallest resource block managed by the caching mechanism. When a system participant attempts to periodically access data that will never be altered by another party, but that data shares a cache block with data that is altered, the caching protocol may force the first participant to reload the whole unit despite a lack of logical necessity. The caching system is unaware of activity within this block and forces the first participant to bear the caching system overhead required by true shared access of a resource." - From Wikipedia
Makes sense, right?
I tried my hand previously at explaining the phenomena in terms of the underlying coherency protocol which boils down to the same issue. These explanations often leave people still confused and I spent some time trying to reduce the explanation so that the idea can get across in a presentation... I'm pretty sure it still left people confused.
Let's try again.
The simplest explanation I've come up with to date is:
  1. Memory is cached at a granularity of a cache line (assumed 64 bytes, which is typical, in the following examples but may be a smaller or larger power of 2, determined by the hardware you run on)
  2. Both reading and writing to a memory location from a particular CPU require the presence of a copy of the memory location in the reading/writing CPU cache. The required location is 'viewed' or cached at the granularity of a cache line.
  3. When a line is not in a threads cache we experience a cache miss as we go searching for a valid copy of it.
  4. Once a line is in our cache it may get evicted (when more memory is required) or invalidated (because a value in that line was changed by another CPU). Otherwise it just stays there.
  5. A write to a cache line invalidates ALL cached copies of that line for ALL CPUs except the writer.
I think there is a mistaken intuition most of us have when it comes to memory access, which is that we think of it as direct. In reality however you access memory through the CPU cache hierarchy and it is in the attempt to make this system coherent and performant that the hardware undoes our intuition. Rather than thinking of all CPUs accessing a global memory pool we should have a mental model that is closer to a distributed version control system as illustrated in this excellent post on memory barriers.
Given the above setting of the stage we can say that false sharing occurs when Thread 1 invalidates (i.e writes to) a cache line required by Thread2 (for reading/writing) even though Thread2 and Thread1 are not accessing the same location.
The cost of false sharing is therefore observable as cache misses, and the cause of false sharing is the write to the cache line (coupled with the granularity of cache coherency). Ergo, the symptom of false sharing can be observed by looking at hardware events for your process or thread:
  • If you are on linux you can use perf. (Checkout the awesome perf integration in JMH!)
  • On linux/windows/mac Intel machines there is PCM.
  • From Java you can use Overseer
  • ... look for hardware counters on google.
Now assuming you have established that the number of cache misses you experience is excessive, the challenge remains in finding the sources of these cache misses. Sadly for Java there is no free utility that I'm aware of which can easily point you to the source of your false sharing problem, C/C++ developers are spoilt for choice by comparison. Some usual suspects to consider however are any shared data constructs, for example queues.


Active False Sharing: Busy Counters

Lets start with a queue with 2 fields which share the same cache line where each field is being updated by a separate thread. In this example we have an SPSC queue with the following structure:
Ignoring the actual correct implementation and edge cases to make this a working queue (you can read more about how that part works here), we can see that offer will be called by one thread, and poll by another as this is an SPSC queue for delivering messages between 2 threads. Each thread will update a distinct field, but as the fields are all jammed tight together we know False Sharing is bound to follow.
The solution at the time of writing seems to be the introduction of padding by means of class inheritance which is covered in detail here. This will add up to an unattractive class as follows:
Yipppeee! the counters are no longer false sharing! That little Pad in the middle will make them feel all fresh and secure.


Passive False Sharing: Hot Neighbours

But the journey is far from over (stay strong), because in False Sharing you don't have to write to a shared cache line to suffer. In the above example both the producer and the consumer are reading the reference to buffer which is sharing a cache line with naughty Mr. consumerIndex. Every time we update consumerIndex an angel loses her wings! As if the wings business wasn't enough, the write also invalidates the cache line for the producer which is trying to read the buffer so that it can write to the damn thing. The solution?
MORE PADDING!!
Surely now everyone will just get along?

The Object Next Door

So now we have the consumer and the producer feverishly updating their respective indexes and we know the indexes are not interfering with each other or with buffer, but what about the objects allocated before/after our queue object? Imagine we allocate 2 instances of the queue above and they end up next to each other in memory, we'd be practically back to where we started with the consumerIndex on the tail end of one object false sharing with the producer index at the head end of the other. In fact, the conclusion we are approaching here is that rapidly mutated fields make very poor neighbours altogether, be it to other fields in the same class or to neighbouring classes. The solution?
EVEN MORE PADDING!!! 
Seems a tad extreme don't it? But hell, at least now we're safe, right?

Buffers are people too
So we have our queue padded like a new born on it's first trip out the house in winter, but what about Miss buffer? Arrays in Java are objects and as such the buffer field merely point to another object and is not inlined into the queue (as it can be in C/C++ for instance). This means the buffer is also subject to potentially causing or suffering from false sharing. This is particularly true for the length field on the array which will get invalidated by writes into the first few elements of the queue, but equally true for any object allocated before or after the array. For circular array queues we know the producer will go around writing to all the elements and come back to the beginning, so the middle elements will be naturally padded. If the array is small enough and the message passing rate is high enough this can have the same effect as any hot field. Alternatively we might experience an uneven behaviour for the queue as the elements around the edges of the array suffer false sharing while the middle ones don't.
Since we cannot extend the array object and pad it to our needs we can over-allocate the buffer and never use the initial/last slots:
We cannot prevent false sharing between neighbours and the array length, what we can do is hoist it into our own class field and use our copy instead of the buffer field. This can also result in better locality if the hoisted length value is hosted in a field alongside the array itself.
Note that this is costing us some computational overhead to compute the offset index instead of the natural one, but in practice we can implement queues such that the we achieve the same effect with no overhead at all.

Protection against the Elements

While on this topic (I do go on about it... hmmm) we can observe that the producer and the consumer threads can still experience false sharing on the cache line holding adjacent elements in the buffer array. This is something we can perhaps handle more effectively if we had arrays of structs in Java (see the value types JEP and structured arrays proposal), and if the queue was to be a queue of such structs. Reality being the terrible place that it is, this is not the case yet. If we could prove our application indeed suffered from this issue, could we solve it?
Yes, but at a questionable price...
If we allocate extra elements for each reference we mean to store in the queue we can use empty elements to pad the used elements. This will reduce the density of each cache line and as a result the probability of false sharing as less and less elements are in a cache line. This comes a high cost however as we multiply the size of the buffer to make room for the empty slots and actively sabotage the memory throughput as we have less data per read cache line. This is an optimization I am reluctant to straight out recommend as a result, but what the hell? sometimes it might helps.

Playing with Dirty Cards

This last one is a nugget and a half. Usually when people say: "It's a JVM/compiler/OS issue" it turns out that it's a code issue written by those same people. But sometimes it is indeed the machine.
In certain cases you might not be the cause of False Sharing. In some cases you might be experiencing False Sharing induced by card marking. I won't spoil it for you, follow the link.

Summary

So there you have it, 6 different cases of False Sharing encountered in the process of optimizing/proofing the piddly SPSC queue. Each one had an impact, some more easily measured than others. The take away here is not "Pad every object and field to death" as that will be detrimental in most cases, much like making every field volatile. But this is an issue worth keeping in mind when writing shared data structures, and in particular when considering highly contended ones.
We've discussed 2 types of False Sharing:

  • Active: where both threads update distinct locations on the same cache line. This will severely impact both threads as they both experience cache misses and cause repeated invalidation of the cache line.
  • Passive: where one thread writes to and another reads from distinct locations on the same cache line. This will have a major impact on the reading thread with many reads resulting in a cache miss. This will also have an impact on the writer as the cache line sharing overhead is experienced.
These were identified and mitigated in several forms:

  1. Neighbouring hot/hot fields (Active)
  2. Neighbouring hot/cold fields (Passive)
  3. Neighbouring objects (potential for both Active and Passive)
  4. Objects neighbouring an array and the array elements (same as 3, but worth highlighting as a subtlety that arrays are separate objects)
  5. Array elements and array length field (Passive as the length is never mutated)
  6. Distinct elements sharing the same cache line (Passive in above example, but normally Active as consumer nulls out the reference on poll)
  7. -XX:+UseCondCardMark - see Dave Dice article

What should you do?
  1. Consider fields concurrently accessed by different threads, in particular frequently written to fields and their neighbours.
  2. Consider Active AND Passive false sharing.
  3. Consider (and be considerate to) your neighbours.
  4. All padding comes at the cost of using up valuable cache space for isolation. If over used (like in the elements padding) performance can suffer.
And finally: love thy neighbour, just a little bit and with adequate protection and appropriate padding, but still love'em.
Belgium! Belgium! Belgium! Belgium! Belgium! Belgium! Belgium! Belgium! Belgium! Belgium! Belgium!

Sunday, 15 September 2013

Diving Deeper into Cache Coherency

I recently gave a talk about Mechnical Sympathy at Facebook, which was mostly a look at the topic through the SPSC queue optimization series of posts. During the talk I presented the optimisation step (taken in Martin's original series of queue implementations) of adding a cache field for the head and tail. Moving from this:

To this:


This change yields a great improvement in throughput which I explained to be down to the reduction in coherency traffic between the cores. This is:
  1. Not what I stated previously here.
  2. A very brief and unsatisfying explanation.
I shall try and remedy that in this post.


Penance

In my original step by step post I explained the benefit of the above optimization is the replacement of a volatile read with a plain read. Martin was kind enough to gently correct me in the comments:
"The "volatile read" is not so much the issue. The real issues come from the read of the head or tail from the opposite end will pretty much always result in a cache miss. This is because the other side is constantly changing it."
and I argued back, stating the JIT compiler can hoist the field into a register and wistfully wishing I could come up with an experiment to prove one way or the other.  I was mostly wrong and Martin was totally right. 
I say mostly and not entirely because eliminating volatile reads is not a bad optimization and is responsible for part of the perf improvement. But it is not the lion share. To prove this point I have hacked the original version to introduce volatile reads (but still plain writes) from the headCache/tailCache fields. I won't bore you with the code, it's using the field offset and Unsafe.getLongVolatile to do it.
I ran the test cross core for 30 times and averaged the summary results. Running on new hardware (so no reference point to prev. quoted results) i7-4700MQ/Ubuntu 13.04/JDK7u25. Here are the results, comparing Original21 (head/tail padded, no cache fields), Original3 (head/tail padded, head/tailCache padded) and VolatileRead (same as Original3, but with volatile read of cache fields):

Original21:     65M ops/sec
Original3:     215M ops/sec
VolatileRead:  198M ops/sec

As we can see, there is no massive difference between Original3 and VolatileRead (especially when considering the difference from Original21), leading me to accept I need to buy Martin a beer, and apologize to any reader of this blog who got the wrong idea reading my post.
Exercise to the reader: I was going to run the above with perf to quantify the impact on cache-misses, but as perf doesn't support this functionality on Haswell I had to let it go. If someone cares to go through the exercise and post a comment it would be most welcome.


What mean cache coherency?

Moving right along, now that we accept the volatile read reduction is not the significant optimization here, let us dig deeper into this cache coherency traffic business. I'll avoid repeating what is well covered elsewhere (like cache-coherence, or MESIF on wikipedia, or this paper, some excellent examples here, and an animation for windows users only here) and summarize:
MESI State Diagram
  • Modern CPUs employ a set of caches to improve memory access latency.
  • To present us with a consistent view of the world when concurrent access to memory happens the caches must communicate to give us a coherent state.
  • There are variations on the protocol used. MESI is the basic one. Recent intels use MESIF. In the examples below I use MESI as the added state in MESIF adds nothing to the use case.
  • The guarantee they go for is basic:
    • One change at a time (to a cache line): A line is never in M state in more than one place. 
    • Let me know if I need a new copy: If I have a copy and someone else changed it I need to get me a new copy. (My copy will move from Shared to Invalid)
All of this happens under the hood of your CPU without you needing to lose any sleep, but if we somehow cause massive amounts of cache coherency traffic then our performance will suffer. One note about the state diagram. The observant reader (thanks Darach) will notice the I to E transition for Processor Write(PW) is in red. This is not my diagram, but I think the reason behind it is that the transition is very far from trivial (or a right pain in the arse really) as demonstrated below.


False Sharing (once more)

False sharing is a manifestation of this issue where 2 threads are competing to write to the same cache line which is constantly Invalid in their own cache.

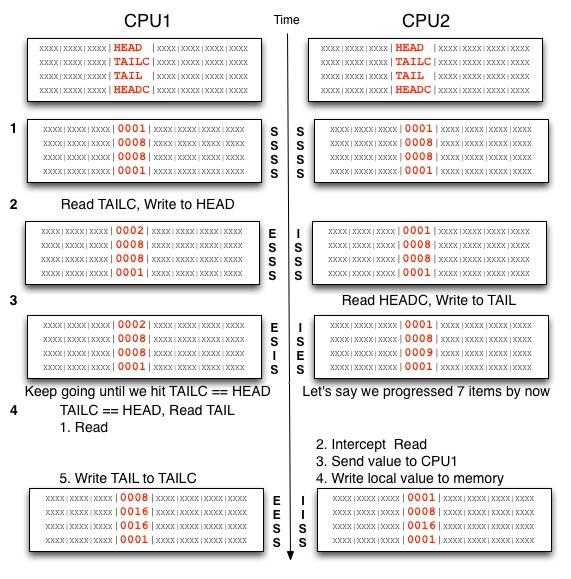
Here's a blow by blow account of false sharing in terms of cache coherency traffic:
  1. Thread1 and Thread2 both have the false Shared cache line in their cache
  2. Thread1 modifies HEAD (state goes from S to E), Thread2's copy is now Invalid
  3. Thread2 wants to modify TAIL but his cache line is now in state I, so experiences a write miss:
    1. Issue a Read With Intent To Modify (RWITM)
    2. RWITM intercepted by Thread1
    3. Thread1 Invalidates own copy
    4. Thread1 writes line to memory
    5. Thread2 re-issues RWITM which results in read from memory (or next layer cache)
  4. Thread1 wants to write to HEAD :( same song and dance again, the above gets in it's way etc.

The diagram to the right is mine, note the numbers on the left track the explanation and the idea was to show the cache lines as they mutate on a timeline. Hope it helps :-).


Reducing Read Misses

So False Sharing is really bad, but this is not about False Sharing (for a change). The principal is similar though. With False Sharing we get Write/Read misses, the above manoeuvre is about eliminating Read misses. This is what happens without the HEADC/TAILC fields (C for cache):
  1. Thread1 and Thread2 both have the HEAD/TAIL  cache lines in Shared state in their cache
  2. Thread1 modifies HEAD (state goes from S to E), Thread2's copy is now Invalid
  3. Thread2 wants to read HEAD to check if the queue wrapped, experiences a Read Miss:
    1. Thread2 issues a request for the HEAD cache line
    2. Read is picked up by Thread1
    3. Thread1 delivers the HEAD cache line to Thread2, the request to memory is dropped
    4. The cache line is written out to main memory and now Thread1/2 have the line in Shared state
This is not as bad as before, but is still far from ideal. The thing is we don't need the latest value of HEAD/TAIL to make progress, it's enough to know that the next increment to our counter is available to be used. So in this use case, caching the head/tail gives us a great win by avoiding all of these Read Misses, we only hit the Read Miss when we run out of progress to be made against our cached values. This looks very different:
  1. Thread1 and Thread2 both have the HEAD/TAIL/HEADC/TAILC  cache lines in Shared state in their cache (the TAILC is only in Thread1, HEADC is only in Thread2, but for symmetry they are included).
  2. Thread1 reads TAILC and modifies HEAD (state goes from S to E), Thread2's copy is now Invalid.
  3. Thread2 reads from HEADC which is not changed. If TAIL is less than HEADC we can make progress (offer elements) with no further delay. This continues until TAIL is equal to HEADC. As long as this is the case HEAD is not read, leaving it in state M in Thread1's cache. Similarly TAIL is kept in state M and Thread2 can make progress. This is when we get the great performance boost as the threads stay out of each others way.
  4. Thread1 now needs to read TAIL to check if the queue wrapped, experiences a Read Miss:
    1. Thread1 issues a request for the TAIL cache line
    2. Request is picked up by Thread2
    3. Thread2 delivers the TAIL cache line to Thread1, the request to memory is dropped
    4. The cache line is written out to main memory and now Thread1/2 have the line in Shared state
    5. TAIL is written to TAILC (TAILC line is now E)
The important thing is that we spend most of our time not needing the latest HEAD value which means Thread2 is not experiencing as many Read Misses, with the added benefit of the threads not having to go back and forth from Shared to Exclusive/Modified state on writes. Once I have a line in the M state I can just keep modifying with no need for any coherence traffic. Also note we never experience a Write Miss.


Summary

In an ideal application (from a cache coherency performance POV) threads never/rarely hit a read or write miss. This translates to having single writers to any piece of data, and minimizing reads to any external data which may be rapidly changing. When we are able to achieve this state we are truly bound by our CPU (rather than memory access).
The takeaway here is: Fast moving data should be in M state as much as possible. A read/write miss by any other thread competing for that line will lead to reverting to S/I which can have significant performance implications. The above example demonstrates how this can achieved by caching stale but usable copies locally to another thread.

Monday, 15 July 2013

Single Producer Single Consumer Queue Revisited: An empiricist tale - part I


{This post is part of a long running series on lock free queues, checkout the full index to get more context here}
Applying lessons learnt about memory layout to prev. discussed SPSC (Single Producer Single Consumer) queue. Tackling and observing some manifestations of false sharing. Getting bitch slapped by reality.

In preparations to implement an MPMC (Many Producers Many Consumers) queue I went back to Martin Thompson's SPSC queue I dissected in detail in this blog post. I was going to use it as the basis for the new queue with a few changes and discuss the transition. In particular an opportunity offered in the implementation of said queue with the addition of the new getAndAdd intrinsic to JDK 8. I was going to... but then I thought, 'let me try a couple more things!' :-).

Where were we?

In case you can't be bothered to go back and read the whole thing again, here's a quick summary. Mr. Thompson open sourced a few samples he discusses in his presentation on lock-free algorithms, in particular a SPSC queue developed across a few stages. I broke down the stages further and benchmarked before and after to explore the effect of each optimisation as it is applied. I then ported the same queue into an off-heap implementation and used it to demonstrate a fast IPC mechanism capable of sending 135M messages per second between processes. The queue demonstrated the following techniques:
Snowman contemplating
evolution
  • lock free, single writer principle observed.
  • Set capacity to power of 2, use mask instead of modulo. 
  • Use lazySet instead of volatile write.
  • Minimize volatile reads by adding local cache fields.
  • Pad all the hot fields: head, tail, headCache,tailCache to avoid false sharing.
So... what's to improve on? There were a few niggles I had looking at this code again, some I've mentioned before. The last time I benchmarked the original queue implementation I noticed high run to run variance in the results. This was particularly prominent when running across 2 cores on the same socket or across sockets.
To expose the variance I modified the test to produce a summary line (each test runs 20 iterations, the summary is the average of the last 10 test iterations) and ran it 30 times. The results demonstrate the variance (results are sorted to highlight the range, X-axis is the run index, Y-axis is a summary of the run, SC means producer and consumer run on the same core, CC means they run across cores on the same socket):


Original queue performance
OUCH! We get half the performance 20% of the time. The results were very stable within a given run, leading me to believe there was a genuine issue at play.

So I thought, let's poke the i's and kick the t's, see if we can shake the variance out of the bugger.

Terms & Conditions

Benchmarks were carried out on a dual socket Xeon running CentOS 6 and Oracle JDK 1.7u17. Affinity was set using taskset, the scripts used are included with the code as well as the raw results and the LibreOffice spread sheets used for the graphs. Furry, fluffy animals were not harmed and people of different religions and races were treated with the outmost respect and afforded equal opportunity. I ran the cross socket tests, and the data is included, but I chose not to discuss them as no improvement was made on that front and they would make this already long post longer. 


Flatten me counters!

To start off, I was not thrilled with the way the counter padding was implemented, for 2 reasons:
  1. By using container classes for the counters we introduce indirection, we could optimise by inlining the data into the queue structure.
  2. The Padded* classes only pad to one side, we are counting on the instances to be laid out together because they are instantiated together. In the right environment I'm pretty sure this can go wrong. By go wrong I mean the instances might get allocated/placed next to data modified elsewhere leading to false sharing. By inlining the counters and forcing strict order we could kill 2 bird with one stone.
To inline the counters, and provide the padding required to provide false-sharing protection I used inheritance to force layout (as outlined previously here). I used Unsafe to get field offset and implement lazySet directly into the fields inlined in my class (this is replacing the original PaddedLong/PaddedAtomicLong, the same method is used in AtomicLong to implement lazySet) the code:

It ain't pretty, but it does the job. The layout can be verified using the excellent java-object-layout tool (I format the output for brevity):
psy.lob.saw.queues.spsc1.SPSCQueue1
 offset  size     type description
      0    12          (assumed to be the object header + first field alignment)
     12     4      int ColdFields.capacity
     16     4      int ColdFields.mask
     20     4 Object[] ColdFields.buffer
     24-72  8     long L1Pad.p10-16
     80     8     long TailField.tail
     88-136 8     long L2Pad.p20-p26
    144     8     long HeadCache.headCache
    152-200 8     long L3Pad.p30-36
    208     8     long HeadField.head
    216-264 8     long L4Pad.p40-46
    272     8     long TailCache.tailCache
    280-328 8     long L5Pad.p50-56
    336                (object boundary, size estimate)

Wicked! Run the same tests above to see what happened:
Original vs. Inlined counters(I1)

We get a small improvement when running on the same core (average 3% improvement), but the cross core behaviour is actually worse. Bummer, keep kicking. 

Padding the class fields

If we look at the above memory layout, we'll notice the fields capacity, mask and buffer are left flush against the object header. This means that they are open to false sharing with other objects/data allocated on the same cache line. We can add a further love handle on that big boy to cover that front:

Note that by happy coincidence we have already padded the tail side of the fields as part of our flattening exercise. So now the layout is:
psy.lob.saw.queues.spsc3.SPSCQueue3
 offset  size     type description
      0    12          (assumed to be the object header + first field alignment)
     12     4          (alignment/padding gap)
     16-72  8     long L0Pad.p00-07
     80     4      int ColdFields.capacity
     84     4      int ColdFields.mask
     88     4 Object[] ColdFields.buffer
     92     4          (alignment/padding gap)
     96-144 8     long L1Pad.p10-16
    152     8     long TailField.tail
    160-208 8     long L2Pad.p20-26
    216     8     long HeadCache.headCache
    224-272 8     long L3Pad.p30-36
    280     8     long HeadField.head
    288-336 8     long L4Pad.p40-46
    344     8     long TailCache.tailCache
    352-400 8     long L5Pad.p50-56
    408                (object boundary, size estimate)

Try again and we get:
Original vs Inlined counters and padded class(I3)


Same single core behaviour as above, but the cross core behaviour looks stable. Sadly the cross core results are worse than the original in many cases. Good thing there is one more trick up our sleeves.

Padding the data

So, this last step may seem a bit over the top, padding the sides of the buffer as well as spacing out all the bloody fields. Surely you must be joking? I padded the buffer by allocating an extra 32 slots to the array and skipping the first 16 on access. The object layout remains the same, you'll have to imagine the extra padding (code is here). But the results are:
Original vs Inlined counters, padded class and padded data(I4)


Run fat Q! Run! This is a nice kick in the single core category (10% increase) and in the cross core it is pretty flat indeed. So when the original behaves they are much the same, but the average result is a 10% improvement. Very little variance remains.

But it's UGLY!

Got me there, indeed it is. Why do we need to go this far to get rid of flaky behaviour? This is one of
Y do we care?
them times when having a direct line to memory management really helps, and Java has always been about you not having to worry about this sort of thing. There is help on the way in the form of the @Contended annotation which would render the above class much nicer, but even then you will need to pad the buffer by yourself. If you look at how the OffHeapQueue manages this issue, you'll see that less padding is required when you know the data alignment. Sadly there is no @Align(size=byte|short|int|long|cache|page) annotation coming anytime soon, and the @Contended annotation is not clear on how you could go about marking an instance rather than a class/field as contended.

Hang on, what if we do it the other way around?

For all you logical minded people out there who think: "we applied the changes together, but not separately. What if this is all about the data padding? we could fix the original without all this fuss...". I feel your pain obsessive brothers. So I went back and added 2 variants, one of a padded data original(referred to as O2 in the graphs) and another of the padded data and inlined fields without the class field padding. I was surprised by the results:

Same Core comparison of data padding impact


Padding the data, of and by itself made things worse for the original implementation and the inlined implementation when running on the same core. Padding the data sucks!
Cross Core comparison of data padding impact
When we look at the cross core results we can see some benefit from the data padding, suggesting it is part of the issue we are trying to solve, but not the whole story.
Padding the cold fields by itself also did little for the performance, as demonstrated above, but removed some of the variance. The 2 put together however gave us some extra performance, and killed the variance issue. Why? I don't know... But there you go, holistic effects of memory layout at work.

A happy ending?

Well... sort of. You see, all the above tests were run with the following JVM options:
-XX:+UseNUMA -XX:+UseCondCardMark -XX:CompileThreshold=100000
And thus the results present a certain truth, but maybe not all of the truth for everyone all of the time... I decided to waste some electricity and rerun some variations of the above options to see what happens. Running with no JVM options I got the following:
Cross core - no JVM opts
  • I4 which is the final inlined version is still quite stable, but it's performance lags behind the other implementations.
  • O1 which is the original implementation has less variance then before (could be luck, who knows) and has the best average result.

Same core - no JVM opts

  • This time I3 (inlined counters, padded class) is the clear winner.
  • I2 (inlined counters, padded data) is second, followed by I4 and I1.
  • When running on the same core, inlining the counters delivers a minor performance win.
Running with -XX:+UseCondCardMark:
ConcCardMark cross core
  • Using CondCardMark has reduced the range somewhat, but still a fair range for all.
  • I4 and I3 are stable, but the overall best average score goes to I1 (133M).
  • I4 is overall slightly better then O1 but worse then O2(original implementation with padded data)
ConcCardMark same core
  • I1 is the best by quite a bit, followed by I4.
Running with -XX:+UseCondCardMark -XX:CompileThreshold=100000:
-XX:+UseCondCardMark -XX:CompileThreshold=100000 - Cross Core
  • With the increased compile threshold O2 has pulled to the top followed by I4 and O1.
  • I4 is looking very much like O1
  • I1, which was the clear winner a second ago, is now rubbish.

-XX:+UseCondCardMark -XX:CompileThreshold=100000 - Same Core
  • On the same core we are seeing now the same behaviour we saw in the beginning.
  • I4 is the clear winner, I1 and I3 pushed down to second place etc.
  • This is odd, why would giving the JIT more data for compilation push the performance of I1 down?
And for comparison the results from -XX:+UseNUMA -XX:+UseCondCardMark -XX:CompileThreshold=100000 presented together:
All together now - Cross Core
  • I4 is the most stable, although O2 has the best overall average throughput.
  • Comparing with all the other combinations we seem to have degraded the performance of other options on our way to find the best option for I4 :(
All together now - Same Core

What does it all mean?

At this point I got quite frustrated. The above approach was producing improvements to the variance, and even an improvement to overall performance on occasion, but the effect was not as decisive and clear as I'd have liked. Some of the variation I just could not shake, even with the best result above I4 is still moving between 110M and 120M and has a spike on either side of this range.
These results are a fine demonstration of how time consuming and error prone the estimation of performance can be. To collect the above results I had to setup the same test to run for each implementation 30 times for each of the affinity options (same core/cross core/cross socket) and repeat
for 4 JVM options combinations (8 impls * 30 runs * 3 affinity setups * 4 JVM_OPTS + extra trial and error runs... = lots of time, quite a bit of data). This result is likely to be different on different hardware, it is likely to change with JDK8, other JVM options and so on. Even with all this effort of collecting data I am very far from having a complete answer. Is this data enough to produce meaningful results/insights at all?
To a certain extent there is evident progress here towards eliminating some of the sources of the run to run variation. Looking at the above results I feel justified in my interpretation of the object layout and the test results. In running the same code on other hardware I've observed good results for I4 and similar variation for the O1, so not all is lost. But this journey is, surprisingly enough, still not over...

More, more, more!

David Hume
If you found this riveting tale of minute implementation changes and their wacky effect on performance absorbing you will love the next chapter in which:
  • I explore cross socket performance and it's implications
  • We contemplate the ownership of memory and it's impact
  • The original implementation is evolved further
  • We hit a high note with 250M ops per second
This post is long enough as is :-)

Wednesday, 15 May 2013

Using JMH to Benchmark Multi-Threaded Code

{UPDATE 03/09/14: If you come here looking for JMH related content start at the new and improved JMH Resources Page and branch out from there!}
Exploring some of the multi-threading related functionality in JMH via a benchmark of false shared counters vs. uncontended counters.
As discussed in previous post the JMH framework introduced by the good folk of the OpenJDK offers a wealth of out of the box functionality to micro benchmark writers. So much in fact that a single post is not enough! In this post I'll explore some of the functionality on offer for people writing and measuring multi-threaded code.

Sharing != Caring?

The phenomena I'm putting under the microscope here is the infamous False Sharing. There are many explanations of what False Sharing is and why it's bad to be found elsewhere(Intel, usenix, Mr. T) but to save you from having to chase links here's mine. Here goes:
In order to maintain memory view consistency across caches modern CPUs must observe which CPU is modifying which location is memory. 2 CPUs modifying the same location are actually sharing and must take turns in doing so leading to contention a much back and forth between the CPUs invalidating each others view on the memory in question. Sadly the protocol used by the CPUs is limited in granularity to cache lines. So when CPU 1 modifies a memory location, the whole cache line (some memory locations to the actual locations right and left) is considered as modified. False sharing occurs when CPU1 and CPU2 are modifying 2 distinct memory locations on the same cache line. They shouldn't interfere with each other, as there is no actual contention, but due to the way cache coherency works they end up uselessly chattering to each other. The image to the right is taken from the Intel link provided above.
I will be using JMH to demonstrate the impact of false sharing by allocating an array of counters and accessing a counter per thread. I am comparing the difference between using all the counters bunched together and spacing them out such that no false sharing happens. I've repeated the same experiment for  plain access, lazySet and volatile access to highlight that false sharing is not limited to memory explicitly involved in multi-threading building blocks.

Multi-Threaded experiments with JMH

JMH offers support for running multi-threaded benchmarks, which is a new feature for such frameworks (to the best of my knowledge). I'll cover some of the available annotations and command line options I used for this benchmark. First up, let's look at the code:

The lazySet and volatile access versions are very similar using an AtomicLongArray instead of the primitive array used above.
In the previous post I briefly described the State annotation and made the most basic use of it. Here's the full description from the javadoc (slightly edited to read as one paragraph here):
State: Marks the state object. State objects naturally encapsulate the state on which benchmark is working on. The Scope of state object defines to which extent it is shared among the worker threads. Three Scope types are supported: 
  • Benchmark: The objects of this scope are always shared between all the threads, and all the identifiers. Note: the state objects of different types are naturally distinct. Setup and TearDown methods on this state object would be performed by one of the worker threads. No other threads would ever touch the state object. 
  • Group: The objects of this scope are shared within the execution group, across all the identifiers of the same type. Setup and TearDown methods on this state object would be performed by one of the group threads. No other threads would ever touch the state object.
  • Thread: The objects of this scope are always unshared, even with multiple identifiers within the same worker thread. Setup and TearDown methods on this state object would be performed by single worker thread exclusively. No other threads would ever touch the state object.
In the above example I'm exploring the use of scoped state further by utilising both Benchmark scope state to store the shared array and a Thread scope state to hold the thread counter index for both the false shared and no sharing case.
The state classes I define are instantiated by JMH rather than directly by my benchmark class. The framework then passes them as parameters to the methods being benchmarked. The only difference between the methods being the use of a different index for accessing the array of counters. As I add more threads, more instances of the Thread state will materialize, but only a single Benchmark state object will be used throughout.

Great Expectations

Before we start looking at what JMH offers us let's consider our expectations of the behaviour under test:
  1. We expect shared and unshared cases to behave the same when there is only a single benchmarking thread.
  2. When there are more than 1 benchmarking threads we expect the unshared case to outperform the shared case.
  3. We expect the unshared case to scale linearly, where the shared case performance should scale badly.
We can put our expectations/theory to the test by running the benchmark and scaling the number of threads participating. JMH offers us several ways to control the number of threads allocated to a benchmark:
  • -t 4 - will launch the benchmark with 4 benchmark threads hitting the code.
  • -tc 1,2,4,8 - will replace both the count of iterations and the number of threads by the thread count pattern described. This example will result in the benchmark being run for 4 iterations, iteration 1 will have 1 benchmarking thread, the second will have 2, the third 4 and the last will have 8 threads.
  • -s - will scale the number of threads per iteration from 1 to the maximum set by -t
I ended up either setting the number of threads directly or using the 'pattern' option. Variety is the spice of life though :-) and its nice to have the choice.
False sharing as a phenomena is a bit random (in Java where memory alignment is hard to control) as it relies on the memory layout falling a particular way on top of the cache line. Consider 2 adjacent memory locations being written to by 2 different threads, should they be placed such that they are on different cache lines in a particular run then that run will not suffer false sharing. This means we'll want to get statistics from a fair amount of runs to make sure we hit the variations we expect on memory layout. JMH supports running multiple forks of your benchmark by using the -f option to determine the number of forks.

And the results are?

Left as an exercise to the reader :-). I implore you to go have a play, come on.
Here's a high level review on my experimentation process for this benchmark:

  • As sanity check, during development I ran the benchmark locally. My laptop is a dual core MBA and is really not a suitable environment for benchmarking, still the results matched the theory although with massive measurement error:
    • Even at this point it was clear the false sharing is a significant issue. Results are consistent, if unstable in their suggestion of how bad it is. 
    • Also as expected, volatile writes are slower than lazy/ordered writes which are slower than plain writes.
  • Once I was happy with the code I deployed it on a more suitable machine. A dual socket Intel Xeon CPU E5-2630 @ 2.30GHz, using OpenJDK 7u9 on CentOS 6.3(OS and JDK are 64bit). This machine has 24 logical cores and is tuned for benchmarking (what that means is a post onto itself). First up I thought I'd go wild and use all the cores, just for the hell of it. Results were interesting if somewhat flaky. 
    • Using all the available CPU power is not a good idea if you want stable results ;-)
  • I decided to pin the process to a single socket and use all it's cores, this leaves plenty of head room for the OS and give me data on scaling up to 12 threads. Nice. At this point I could have a meaningful run with 1,2,4,8,12 threads to see the way false sharing hurts scaling for the different write methods. At this point things started to get more interesting:
    • Volatile writes suffering from false sharing degrade in overall performance as more threads are added, 12 threads suffering from false sharing achieve less than 1 thread. 
    • Once false sharing is resolved volatile writes scale near linearly until 8 threads, the same is true for lazy and plain. 8 to 12 seem to not scale quite so cleanly.
    • Lazy/Plain writes do not suffer quite as much from false sharing but the more threads are at work the larger the difference (up to 2.5x) becomes between false sharing and unshared.
    Scaling from 1-12 threads
  • I focused on the 12 thread case, running longer/more iterations and observing the output, it soon became clear the results for the false shared access suffer from high run-to-run variance. The reason for that, I assumed, was the different memory layout from run to run resulting in different cache line populations. In the case of 12 threads we have 12 adjacent longs. Given the cache line is 8 longs wide they can be distributed over 2 or 3 lines in a number of ways (2-8-2,1-8-3,8-4,7-5,6-6). Going ever deeper into the rabbit hole I thought I could print out the thread specific stats (choose -otss, JMH delivers again :-) ). The thread stats did deliver a wealth of information, but at this point I hit slight disappointment... There was no (easy) way for me to correlate thread numbers from the run to thread numbers in the output, which would have made my life slightly easier in characterising the different distributions...
  • I had enough and played with the data until I was happy with the results. And I finally found a use for a stacked bar chart :-). Each thread score is a different color, the sum of all thread scores is the overall score.
Here's the results for plain/volatile shared/unshared running on 12 cores (20 runs, 5 iterations per run: -f 20 -i 5 -r 1):
Plain writes suffering from false sharing. Note the different threads score
differently and the overall result falls into several different 'categories'.
Plain writes with no false sharing. Threads score is fairly uniform,
and overall score is stable.
Volatile writes suffering from false sharing, note the score varies
by less than it did in the plain write case but similar categories emerge.
Volatile writes with no false sharing, similarly uniform behaviour
for all threads.
Hope you enjoyed the pictures :-)

UPDATE (1/08/2013): If you are looking for more JMH related info, see Shipilev's slides from JVMLS.
UPDATE (1/07/2014): The samples repository has been updated to reflect JMH progress, sample code may have minor differences from the code presented above and command line options may differ. I will follow up at some point with a re-vamp of JMH related posts but for now you can always reproduce above results by reviving the older code from history.

Sunday, 7 April 2013

135 Million messages a second between processes in pure Java

{This post is part of a long running series on lock free queues, checkout the full index to get more context here}
Porting an existing single producer/single consumer concurrent queue into an IPC mechanism via memory mapped files and getting 135 million messages throughput in pure Java.
In my previous post I covered a single producer/consumer queue developed and shared by Martin Thompson capable of delivering an amazing 130M messages per second. The queue he delivered is a great tool for communicating between threads, but sometimes communicating between threads is not enough. Sometime you need to leave your JVM and go out of process. Inter Process Communications (IPC) is a different problem to inter thread communications, can it be cracked by the same approach?

IPC, what's the problem?

Inter Process Communication is an old problem and there are many ways to solve it (which I will not discuss here). There are several attractions to specialized IPC solutions for Java:
  • Faster than socket communication.
  • An out of process integration option with applications written in other languages.
  • A means of splitting large VMs to smaller ones improving performance by allowing GC and JIT specialization.
For IPC to be attractive it has to be fast, otherwise you may as well go for network based solutions which would extend beyond your local machine uniformly. I attended an Informatica conference a while back and got talking to Todd Montgomerey about the Disruptor and mechanical sympathy, he suggested that IPC should be able to perform as well as inter thread messaging. I found the idea interesting and originally meant to port the Disruptor, but Martin's queue is simpler (and quicker) so I went for that instead. Starting with a good algorithm/data structure is very good indeed, now I just needed to bridge the gap and see if I can maintain the benefits.


Off the heap we go!

To do IPC we must go off heap. This has several implications for the queue, most importantly references are not supported. Also note persistence to and from the queue is required, though one could extend my implementation to support a zero copy interaction where a struct is acquired, written and committed instead of the offer method, and similarly acquired, read and finally released instead of the poll method. I plan to make several flavours of this queue to test out these ideas in the near future.
My IPC queue uses a memory mapped file as a means of acquiring a chunk of shared memory, there is no intention to use the persisted values though further development in that direction may prove interesting to some. So now that I got me some shared memory, I had to put the queue in it.
I started by laying out the queue counters and cached counters. After realizing the counters need to be aligned to work properly I learnt how to align memory in Java. I went on to verify that aligned memory offers the guarantees required for concurrent access. Quick summary:
  • aligned access means writing data types to addresses which divide by their size.
  • unaligned access is not atomic, which is bad for concurrency :(
  • unaligned access is slow, which is bad for performance :(
  • unaligned access may not work, depending on OS and architecture. Not working is very bad :(
Sorting out alignment is not such a big deal once you know how it works. One of the nice things about going off-heap was that solving false sharing has become far more straightforward. Move your pointer and you're in the next cache line, job done. This left me rather frustrated me with the tricks required to control memory layout in Java. Going back to the original implementation you will notice the Padded classes who's role it is to offer false sharing protection. They are glorious hacks (with all due respect) made necessary by this lack of control. The @Contended annotation coming in JDK 8 will hopefully remove the need for this.
This is how the memory layout worked out:


To illustrate in glorious ASCII graphics (each - is a byte), this is what the memory layout looks like when broken into cache lines:
|--------|--------|--------|head....|--------|--------|--------|--------|
|--------|--------|--------|tailCach|--------|--------|--------|--------|
|--------|--------|--------|tail----|--------|--------|--------|--------|
|--------|--------|--------|headCach|--------|--------|--------|--------|
|int1int2|int3int4|int5int6|etcetcet|cetcetce|tcetcetc|etcetcet|cetcetce|
...


I played around with mixing off heap counters with on heap buffer but in the interest of brevity I'll summarize and say the JVM does not like that very much and the end result performance is not as good as all heap/off-heap solutions. The code is available with everything else.
Once alignment and memory layout were sorted I had to give up the flexibility of having reference pointers and settle for writing my data (an integer) directly into the memory. This leaves my queue very restrictive in it's current form. I intend to revisit it and see what I can do to offer a more extendable API on top of it.
Let me summarize the recipe at this point:
  • Create a memory mapped file large enough to hold:
    • 4 cache lines for counters/cached counters.
    • 4 bytes(per integer) * queue capacity (must be a power of 2).
    • 1 spare cache line to ensure you can align the above to the cache line.
  • Get a mapped byte buffer, which is a direct byte buffer on top of the mapped memory.
  • Steal the address and get the contained aligned byte buffer.
  • Setup pointers to the counters and the beginning of the buffer
  • Replace use of natural counters with off heap counters accessed via Unsafe using the pointers.
  • Replace use of array with use of offset pointers into buffer and Unsafe access.
  • Test and debug until you work out the kinks...
The above code should give you a fair idea how it works out and the rest is here. This queue can work in process and out of process as demonstrated in the tests included in the repository. Now that it works (for the limited use case, and with room for further improvement... but works), is it fast enough? not so fast? is it...<gasp> ... FASTER????!?!?!

Smithers, release the hounds

Here are the numbers for using the different implementations in process:

Implementation/AffinitySame coreCross coreCross socket
P1C1QueueOriginal3110M130M19M
P1C1OffHeapQueue130M220M200M
P1C1QueueOriginalPrimitive124M220M215M


Confused? Let me explain. First line is the measurements taken for the original queue. Similar to what was presented in prev. post, though I saw a slight improvement in the results with increasing the compile threshold to 100000.
The second line is my offheap implementation of same algorithm. It is significantly faster. This is not IPC yet, this is in process. The reason it is faster is because data is inlined in the queue, which means that by loading an entry in the queue we get the data as opposed to a reference to the data. Getting a reference is what you get when you have and Object[] array. The array holds the references and the data is elsewhere, this seems to make it more painful as we get further from the producer.
The last entry is a mutation of P1C1QueueOriginal3 into a primitive array backed queue to compare performance like for like. As you can see this displays very similar results to the off heap implementation supporting the theory that data in-lining is behind the observed performance boost.
The lesson here is an old one, namely that pointer chasing is expensive business further amplified by the distance between the producing CPU and consuming CPU.
The off-heap queue can offer an alternative to native code integration as the consuming thread may interact directly with the off-heap queue and write results back to a different off-heap queue.
Running a similar benchmark adapted to use a memory mapped file as the backing DirectByteBuffer for the off-heap queue we get:
    same core      - ops/sec=135M
    across cores   - ops/sec=98M
    across sockets - ops/sec=25M


JOY! a pure Java IPC that gives you 135M messages per second is more throughput then you'd get with most commercial products out there. This is still not as fast as the same queue in process and I admit I'm not sure what the source of the performance difference is. Still I am quite happy with it.
A few notes/observations from the experimentation process:
  1. I got a variety of results, stabilizing around different average throughputs. I chose the best for the above summary and plan to go into detail about the results in the near future.
  2. The JVM was launched with: -XX:+UseCondCardMark -XX:CompileThreshold=100000
  3. Removing the Thread.yield from the producer/consumer loops improved performance when running on the same core, but made it worse otherwise.
  4. Moving the queue allocation into the test loop changes the performance profile dramatically.
  5. I've not had time to fully explore the size of the queue as a variable in the experiment but the little I've done suggests it makes a difference, choose the right size for your application.
I realize this post is rather less accessible than the previous one, so if you have any questions please ask.